Training a custom scAdam model#
scAdam is a multi-level automatic cell type annotation model implemented in the scParadise package. It assigns biologically interpretable cell-type labels to single-cell RNA-seq data and supports annotation across multiple levels of cellular hierarchy, from broad cell classes to more specific cell populations.
This tutorial demonstrates how to train a custom scAdam model using a user-defined reference dataset and cell-type hierarchy. You will learn how to prepare annotated training data, configure and train the model and evaluate its annotation performance.
[1]:
# Python packages
import warnings
warnings.simplefilter('ignore')

import scanpy as sc
import scparadise
import seaborn as sns
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd

sc.set_figure_params(dpi = 120)
Recommendations about training dataset#
Our models were tested on data normalized using the shifted logarithm method. Therefore, we recommend applying the same normalization method when training your own models.
sc.pp.normalize_total(adata, target_sum=None)
sc.pp.log1p(adata)
However, you may use another normalization method, provided that the same method is applied consistently to both the training and test datasets.
Ensure that adata_train.X contains all genes selected as input features for model training.
We recommend excluding genes that are not included in the selected marker-gene set from adata_train.X. Removing uninformative features may improve model performance and evaluation metrics.
Data preparation#
Here we download and preprocess dataset from cellxgene:
Single cell RNA sequencing of oropharyngeal squamous cell carcinoma https://cellxgene.cziscience.com/collections/3c34e6f1-6827-47dd-8e19-9edcd461893f
[2]:
!wget https://datasets.cellxgene.cziscience.com/915069db-1df2-49a1-9a9c-2fbd0aa13c81.h5ad
--2025-01-16 12:42:52--  https://datasets.cellxgene.cziscience.com/915069db-1df2-49a1-9a9c-2fbd0aa13c81.h5ad
Resolving datasets.cellxgene.cziscience.com (datasets.cellxgene.cziscience.com)... 52.85.49.125, 52.85.49.28, 52.85.49.24, ...
Connecting to datasets.cellxgene.cziscience.com (datasets.cellxgene.cziscience.com)|52.85.49.125|:443... connected.
HTTP request sent, awaiting response... 200 OK
Length: 981941987 (936M) [binary/octet-stream]
Saving to: ‘915069db-1df2-49a1-9a9c-2fbd0aa13c81.h5ad’

915069db-1df2-49a1- 100%[===================>] 936.45M  4.91MB/s    in 2m 16s

2025-01-16 12:45:08 (6.89 MB/s) - ‘915069db-1df2-49a1-9a9c-2fbd0aa13c81.h5ad’ saved [981941987/981941987]
[3]:
# Load prepared for training anndata object
adata = sc.read_h5ad('915069db-1df2-49a1-9a9c-2fbd0aa13c81.h5ad')
[4]:
# Get raw counts from adata.raw
adata = adata.raw.to_adata()
[5]:
# Use gene symbols rather than Ensembl gene IDs (ENSG identifiers).
adata.var.set_index('feature_name', inplace=True)
adata.var_names_make_unique()
To implement the example of training a model for multi-level cell-type annotation, we will define two levels of cell-type annotations.
[6]:
# Create celltype_l1 and celltype_l2 annotation levels
adata.obs['celltype_l2'] = adata.obs['cell_type'].copy()
# Check current cluster name
cluster_list = adata.obs['celltype_l2'].unique()
# Make cluster anottation dictionary
annotation = {
    "Epithelial": ['epithelial cell'],
    "B": ['B cell', 'plasma cell'],
    "T": ['CD4-positive, alpha-beta T cell', 'CD8-positive, alpha-beta T cell', 'mature alpha-beta T cell', 'regulatory T cell'],
    "NK": ['natural killer cell'],
    "Myeloid": ['myeloid cell', 'plasmacytoid dendritic cell', 'mast cell'],
    "Endothelial": ['endothelial cell', 'endothelial cell of lymphatic vessel'],
    "Stromal": ['fibroblast', 'mural cell']
}

# Change dictionary format
annotation_rev = {}
for i in cluster_list:
    for k in annotation:
        if i in annotation[k]:
            annotation_rev[i] = k

adata.obs["celltype_l1"] = [annotation_rev[i] for i in adata.obs['celltype_l2']]
[7]:
# Check annotations
sc.pl.umap(
    adata,
    color = [
        'celltype_l1',
        'celltype_l2'
    ],
    frameon = False,
    ncols = 1
)

[8]:
# Create adata_train1, adata_train2 and adata_test datasets
adata_test = adata[adata.obs['donor_id'].isin(['HN481', 'HN482'])].copy()
adata_train = adata[adata.obs['donor_id'].isin(['HN483' 'HN485', 'HN488', 'HN489', 'HN490', 'HN487', 'HN492', 'HN494'])].copy()
del adata
[9]:
# Normalize data
for i in [adata_train, adata_test]:
    i.layers['counts'] = i.X.copy()
    sc.pp.normalize_total(i, target_sum=None)
    sc.pp.log1p(i)
[10]:
# Find highly variable features for scAdam model training
sc.pp.highly_variable_genes(
    adata_train,
    layer='counts',
    flavor='seurat_v3',
    n_top_genes=1200,
    subset=True
)
Balanced training#
We recommend balancing the dataset based on the most detailed annotation level—the last entry in the celltype_keys list, which is celltype_l2 in this example. Balancing the training dataset can improve sensitivity, balanced accuracy, F1 score, and geometric mean, but may lead to a slight decrease in precision.
[11]:
# Balance dataset based on most detailed annotation level
adata_balanced = scparadise.scnoah.balance(
    adata_train,
    celltype_keys = ['celltype_l1', 'celltype_l2']
)
[12]:
# Train scadam model using adata_balanced dataset
scparadise.scadam.train(
    adata_balanced,
    path = '', # path to save model
    model_name = 'model_scadam_balanced', # folder name with model
    celltype_keys = [
        'celltype_l1', # First (less detailed) annotation level
        'celltype_l2', # Second (most detailed) annotation level
    ],
    eval_metric = ['accuracy', 'balanced_accuracy']
)
Device: cuda
Number of features: 1200
Label hierarchy: celltype_l1 → celltype_l2
Annotation levels weights using strategy 'linear_offset':
  celltype_l1: 7 cell types, 0.4 relative weight
  celltype_l2: 15 cell types, 0.6 relative weight

Dataset split:
Train dataset contains: 36904 cells, it is 80.0 % of input dataset
Validation dataset contains: 9226 cells, it is 20.0 % of input dataset
Unsupervised pretraining: 100%|████████████████| 50/50 [06:00<00:00,  7.21s/it]
Training scAdam model:   9%|█▌                | 18/200 [02:14<22:42,  7.49s/it]
Early stopping triggered! Best score: 0.9793
Training completed!
Fitting unknown cells detector
UnknownCellDetector fitted successfully!
Model saved to model_scadam_balanced
Check model quality#
[13]:
# Predict cell types using trained model
adata_test = scparadise.scadam.predict(
    adata_test,
    path_model = 'model_scadam_balanced'
)
Cell type annotation using the 2nd version of the scAdam model
scAdam model with unknown detector loaded from model_scadam_balanced
Gene alignment:
  Model features: 1200
  Matched features: 1200 (100.0%)
Predicting: 100%|█████████████████████████████| 72/72 [00:00<00:00, 170.65it/s]
Added cell type column: pred_celltype_l1
Added probabilities column: pred_celltype_l1_probability
Added cell type column: pred_celltype_l2
Added probabilities column: pred_celltype_l2_probability
[14]:
# Add prediction status to adata_test
for i in ['l1', 'l2']:
    scparadise.scnoah.pred_status(
        adata_test,
        celltype = 'celltype_' + i,
        pred_celltype = 'pred_celltype_' + i,
        key_added = 'pred_status_' + i
    )
[15]:
# Order cell type colors
for i in ['l1', 'l2']:
    celltype = np.unique(adata_test.obs['celltype_' + i]).tolist()
    adata_test.obs['celltype_' + i] = pd.Categorical(
        values=adata_test.obs['celltype_' + i], categories=celltype, ordered=True
    )
    adata_test.obs['pred_celltype_' + i] = pd.Categorical(
        values=adata_test.obs['pred_celltype_' + i], categories=celltype, ordered=True
    )
[16]:
# Visualise predicted cell types (celltype_l1) and prediction probabilities
sc.pl.umap(
    adata_test,
    color=[
        'celltype_l1', # observed cell type annotations
        'pred_celltype_l1', # predicted cell type annotations
        'pred_celltype_l1_probability' # prediction probabilities
    ],
    frameon = False,
    cmap = 'viridis',
    legend_loc = 'right margin',
    legend_fontsize = 7,
    legend_fontoutline = 1,
    ncols = 3,
    wspace = 0.2,
    hspace = 0.1
)
[17]:
# Visualise predicted cell types (celltype_l2) and prediction probabilities
sc.pl.umap(
    adata_test,
    color=[
        'celltype_l2', # observed cell type annotations
        'pred_celltype_l2', # predicted cell type annotations
        'pred_celltype_l2_probability' # prediction probabilities
    ],
    frameon = False,
    cmap = 'viridis',
    legend_loc = 'right margin',
    legend_fontsize = 5,
    legend_fontoutline = 1,
    ncols = 2,
    wspace = 0.6,
    hspace = 0.1
)

[18]:
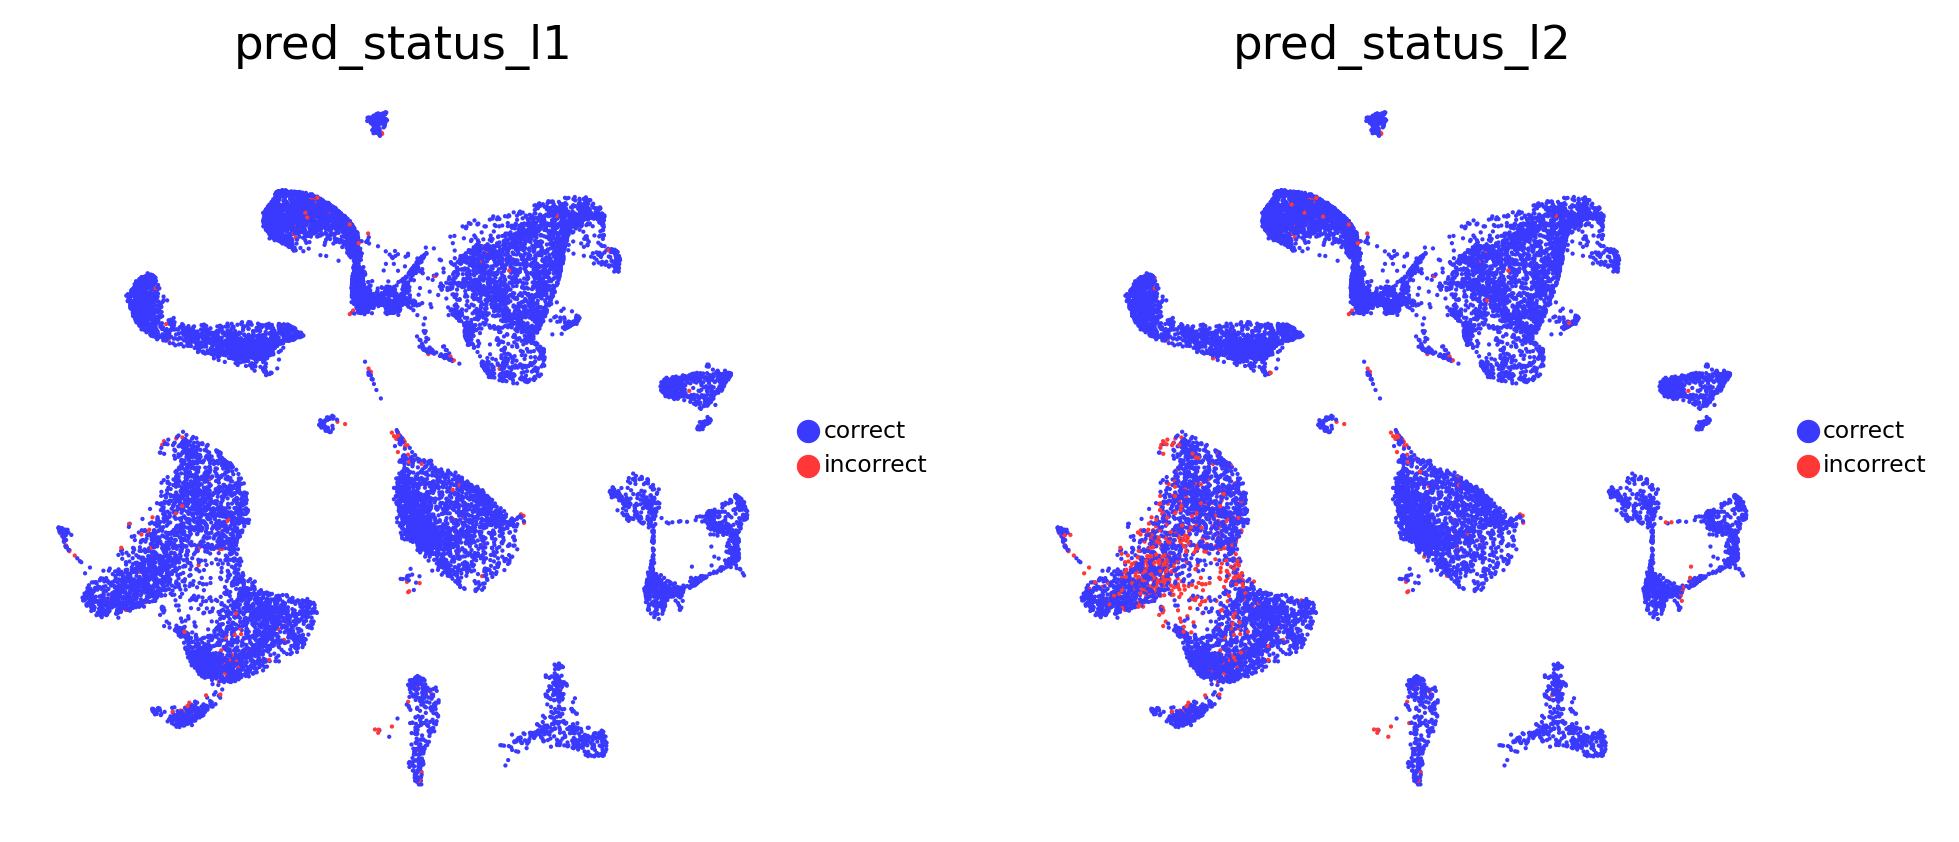
# Visualise prediction status
sc.pl.embedding(
    adata_test,
    color=[
        'pred_status_l1',
        'pred_status_l2'
    ],
    basis = 'X_umap',
    frameon = False,
    cmap = 'viridis',
    legend_loc = 'right margin',
    legend_fontsize = 7,
    legend_fontoutline = 1,
    ncols = 3,
    wspace = 0.2,
    hspace = 0.1
)

The probability and prediction status analysis indicates issues with the model in annotating T cell subtypes at the celltype_l2 annotation level. However, the model does not have problems with annotating other cell types, as confirmed by the quality analysis presented below.
Comparizon of observed and predicted cell type annotations#
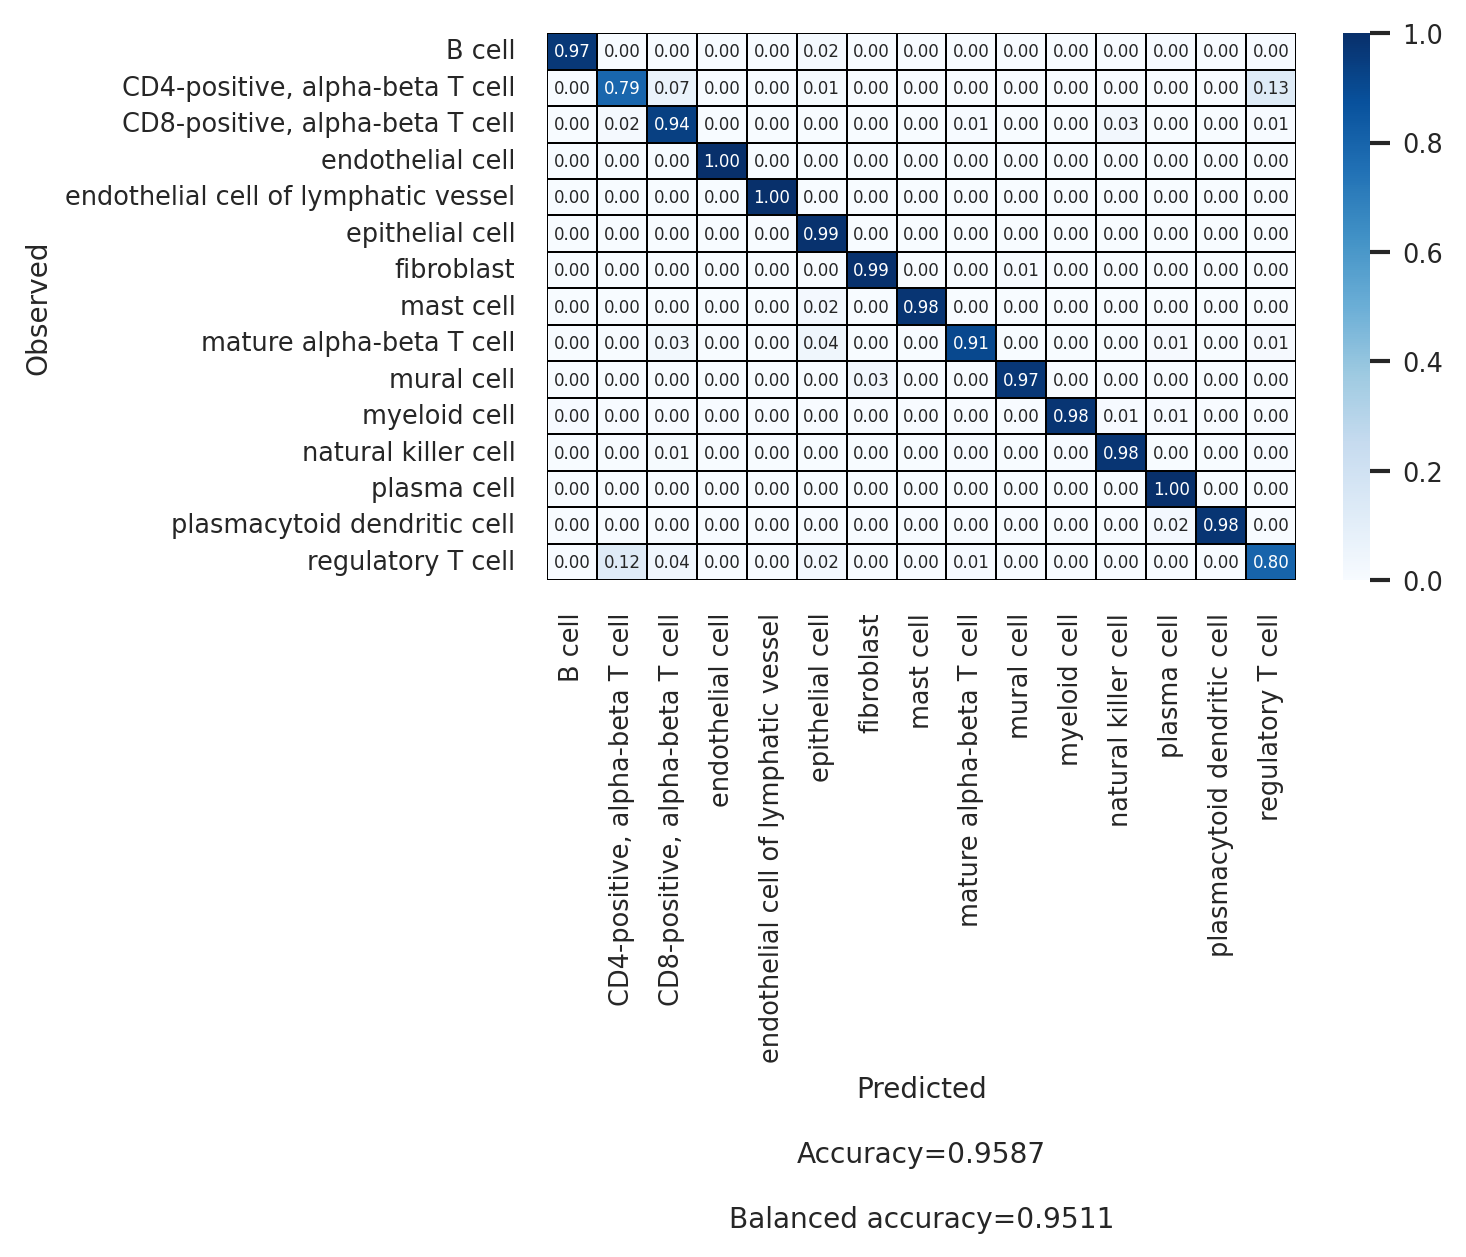
To compare the actual and predicted cell types, we use report_classif_full and conf_matrix from the scNoah module. More information about the metrics in scparadise.scnoah.report_classif_full is available in the scParadise documentation. More information about confusion matrix (scparadise.scnoah.conf_matrix) is available
here.
[19]:
# First annotation level (celltype_l1)
df_l1 = scparadise.scnoah.report_classif_full(
    adata_test,
    celltype = 'celltype_l1',
    pred_celltype = 'pred_celltype_l1',
    ndigits = 3
)
df_l1
[19]:
| precision | recall/sensitivity | specificity | f1-score | geometric mean | index balanced accuracy | number of cells | |
|---|---|---|---|---|---|---|---|
| B | 0.991 | 0.986 | 0.998 | 0.989 | 0.992 | 0.983 | 3969 |
| Endothelial | 0.998 | 0.998 | 1.0 | 0.998 | 0.999 | 0.998 | 509 |
| Epithelial | 0.992 | 0.99 | 0.994 | 0.991 | 0.992 | 0.984 | 7505 |
| Myeloid | 0.979 | 0.981 | 0.999 | 0.98 | 0.99 | 0.978 | 924 |
| NK | 0.843 | 0.96 | 0.998 | 0.897 | 0.979 | 0.954 | 223 |
| Stromal | 0.999 | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | 1113 |
| T | 0.979 | 0.979 | 0.994 | 0.979 | 0.987 | 0.972 | 4057 |
| macro avg | 0.969 | 0.985 | 0.998 | 0.976 | 0.991 | 0.981 | |
| weighted avg | 0.987 | 0.987 | 0.996 | 0.987 | 0.991 | 0.982 | |
| Accuracy | 0.987 | ||||||
| Balanced accuracy | 0.985 |
[20]:
sns.set(font_scale = 0.7)
plt.figure(figsize = (3, 3))
scparadise.scnoah.conf_matrix(
    adata_test,
    celltype = 'celltype_l1',
    pred_celltype = 'pred_celltype_l1',
    annot_kws = {"size":5},
    linewidths = 0.1, linecolor = 'black',
    fmt =  ".2f",
    ndigits_metrics = 4,
    vmin = 0, vmax = 1
)
[21]:
# Second annotation level (celltype_l2)
df_l2 = scparadise.scnoah.report_classif_full(
    adata_test,
    celltype = 'celltype_l2',
    pred_celltype = 'pred_celltype_l2',
    ndigits = 3
)
df_l2
[21]:
| precision | recall/sensitivity | specificity | f1-score | geometric mean | index balanced accuracy | number of cells | |
|---|---|---|---|---|---|---|---|
| B cell | 0.995 | 0.971 | 0.999 | 0.983 | 0.985 | 0.968 | 2050 |
| CD4-positive, alpha-beta T cell | 0.861 | 0.801 | 0.988 | 0.83 | 0.89 | 0.777 | 1554 |
| CD8-positive, alpha-beta T cell | 0.917 | 0.949 | 0.991 | 0.933 | 0.97 | 0.936 | 1742 |
| endothelial cell | 0.996 | 1.0 | 1.0 | 0.998 | 1.0 | 1.0 | 457 |
| endothelial cell of lymphatic vessel | 1.000 | 0.981 | 1.0 | 0.99 | 0.99 | 0.979 | 52 |
| epithelial cell | 0.991 | 0.991 | 0.994 | 0.991 | 0.992 | 0.985 | 7505 |
| fibroblast | 0.982 | 0.994 | 0.999 | 0.988 | 0.997 | 0.993 | 676 |
| mast cell | 0.986 | 0.986 | 1.0 | 0.986 | 0.993 | 0.985 | 148 |
| mature alpha-beta T cell | 0.868 | 0.88 | 0.999 | 0.874 | 0.938 | 0.869 | 75 |
| mural cell | 0.991 | 0.973 | 1.0 | 0.982 | 0.986 | 0.97 | 437 |
| myeloid cell | 0.987 | 0.975 | 0.999 | 0.981 | 0.987 | 0.972 | 726 |
| natural killer cell | 0.830 | 0.964 | 0.998 | 0.892 | 0.981 | 0.959 | 223 |
| plasma cell | 0.985 | 0.997 | 0.998 | 0.991 | 0.998 | 0.996 | 1919 |
| plasmacytoid dendritic cell | 0.980 | 0.98 | 1.0 | 0.98 | 0.99 | 0.978 | 50 |
| regulatory T cell | 0.707 | 0.757 | 0.988 | 0.731 | 0.864 | 0.73 | 686 |
| macro avg | 0.939 | 0.947 | 0.997 | 0.942 | 0.971 | 0.94 | |
| weighted avg | 0.959 | 0.959 | 0.995 | 0.959 | 0.976 | 0.951 | |
| Accuracy | 0.959 | ||||||
| Balanced accuracy | 0.947 |
[22]:
sns.set(font_scale = 0.7)
plt.figure(figsize = (5, 3))
scparadise.scnoah.conf_matrix(
    adata_test,
    celltype = 'celltype_l2',
    pred_celltype = 'pred_celltype_l2',
    annot_kws = {"size":5},
    linewidths = 0.1, linecolor = 'black',
    fmt =  ".2f",
    ndigits_metrics = 4,
    vmin = 0, vmax = 1
)

[23]:
# Save anndata with predicted annotations
adata_test.write_h5ad('adata_test_balanced_model.h5ad')
Imbalanced training#
Use ‘balanced_accuracy’ as evaluation metric in case of imbalanced learning
[24]:
# Train scadam model using adata_train dataset
scparadise.scadam.train(
    adata_balanced,
    path = '', # path to save model
    model_name = 'model_scadam_imbalanced', # folder name with model
    celltype_keys = [
        'celltype_l1', # First (less detailed) annotation level
        'celltype_l2', # Second (most detailed) annotation level
    ],
    eval_metric = ['accuracy', 'balanced_accuracy']
)
Device: cuda
Number of features: 1200
Label hierarchy: celltype_l1 → celltype_l2
Annotation levels weights using strategy 'linear_offset':
  celltype_l1: 7 cell types, 0.4 relative weight
  celltype_l2: 15 cell types, 0.6 relative weight

Dataset split:
Train dataset contains: 36904 cells, it is 80.0 % of input dataset
Validation dataset contains: 9226 cells, it is 20.0 % of input dataset
Unsupervised pretraining: 100%|████████████████| 50/50 [05:22<00:00,  6.45s/it]
Training scAdam model:   9%|█▌                | 18/200 [02:13<22:34,  7.44s/it]
Early stopping triggered! Best score: 0.9793
Training completed!
Fitting unknown cells detector
UnknownCellDetector fitted successfully!
Model saved to model_scadam_imbalanced
Check model quality#
[25]:
# Predict cell types using trained model
adata_test = scparadise.scadam.predict(
    adata_test,
    path_model = 'model_scadam_imbalanced'
)
Cell type annotation using the 2nd version of the scAdam model
scAdam model with unknown detector loaded from model_scadam_imbalanced
Gene alignment:
  Model features: 1200
  Matched features: 1200 (100.0%)
Predicting: 100%|█████████████████████████████| 72/72 [00:00<00:00, 152.04it/s]
Added cell type column: pred_celltype_l1
Added probabilities column: pred_celltype_l1_probability
Added cell type column: pred_celltype_l2
Added probabilities column: pred_celltype_l2_probability
[26]:
# Add prediction status to adata_test
for i in ['l1', 'l2']:
    scparadise.scnoah.pred_status(
        adata_test,
        celltype = 'celltype_' + i,
        pred_celltype = 'pred_celltype_' + i,
        key_added = 'pred_status_' + i
    )
[27]:
# Order cell type colors
for i in ['l1', 'l2']:
    celltype = np.unique(adata_test.obs['celltype_' + i]).tolist()
    adata_test.obs['celltype_' + i] = pd.Categorical(
        values=adata_test.obs['celltype_' + i], categories=celltype, ordered=True
    )
    adata_test.obs['pred_celltype_' + i] = pd.Categorical(
        values=adata_test.obs['pred_celltype_' + i], categories=celltype, ordered=True
    )
[28]:
# Visualise predicted cell types (celltype_l1) and prediction probabilities
sc.pl.umap(
    adata_test,
    color=[
        'celltype_l1', # observed cell type annotations
        'pred_celltype_l1', # predicted cell type annotations
        'pred_celltype_l1_probability' # prediction probabilities
    ],
    frameon = False,
    cmap = 'viridis',
    legend_loc = 'right margin',
    legend_fontsize = 7,
    legend_fontoutline = 1,
    ncols = 3,
    wspace = 0.2,
    hspace = 0.1
)
[29]:
# Visualise predicted cell types (celltype_l2) and prediction probabilities
sc.pl.umap(
    adata_test,
    color=[
        'celltype_l2', # observed cell type annotations
        'pred_celltype_l2', # predicted cell type annotations
        'pred_celltype_l2_probability' # prediction probabilities
    ],
    frameon = False,
    cmap = 'viridis',
    legend_loc = 'right margin',
    legend_fontsize = 5,
    legend_fontoutline = 1,
    ncols = 2,
    wspace = 0.5,
    hspace = 0.1
)

[30]:
# Visualise prediction status
sc.pl.embedding(
    adata_test,
    color=[
        'pred_status_l1',
        'pred_status_l2'
    ],
    basis = 'X_umap',
    frameon = False,
    cmap = 'viridis',
    legend_loc = 'right margin',
    legend_fontsize = 7,
    legend_fontoutline = 1,
    ncols = 3,
    wspace = 0.2,
    hspace = 0.1
)

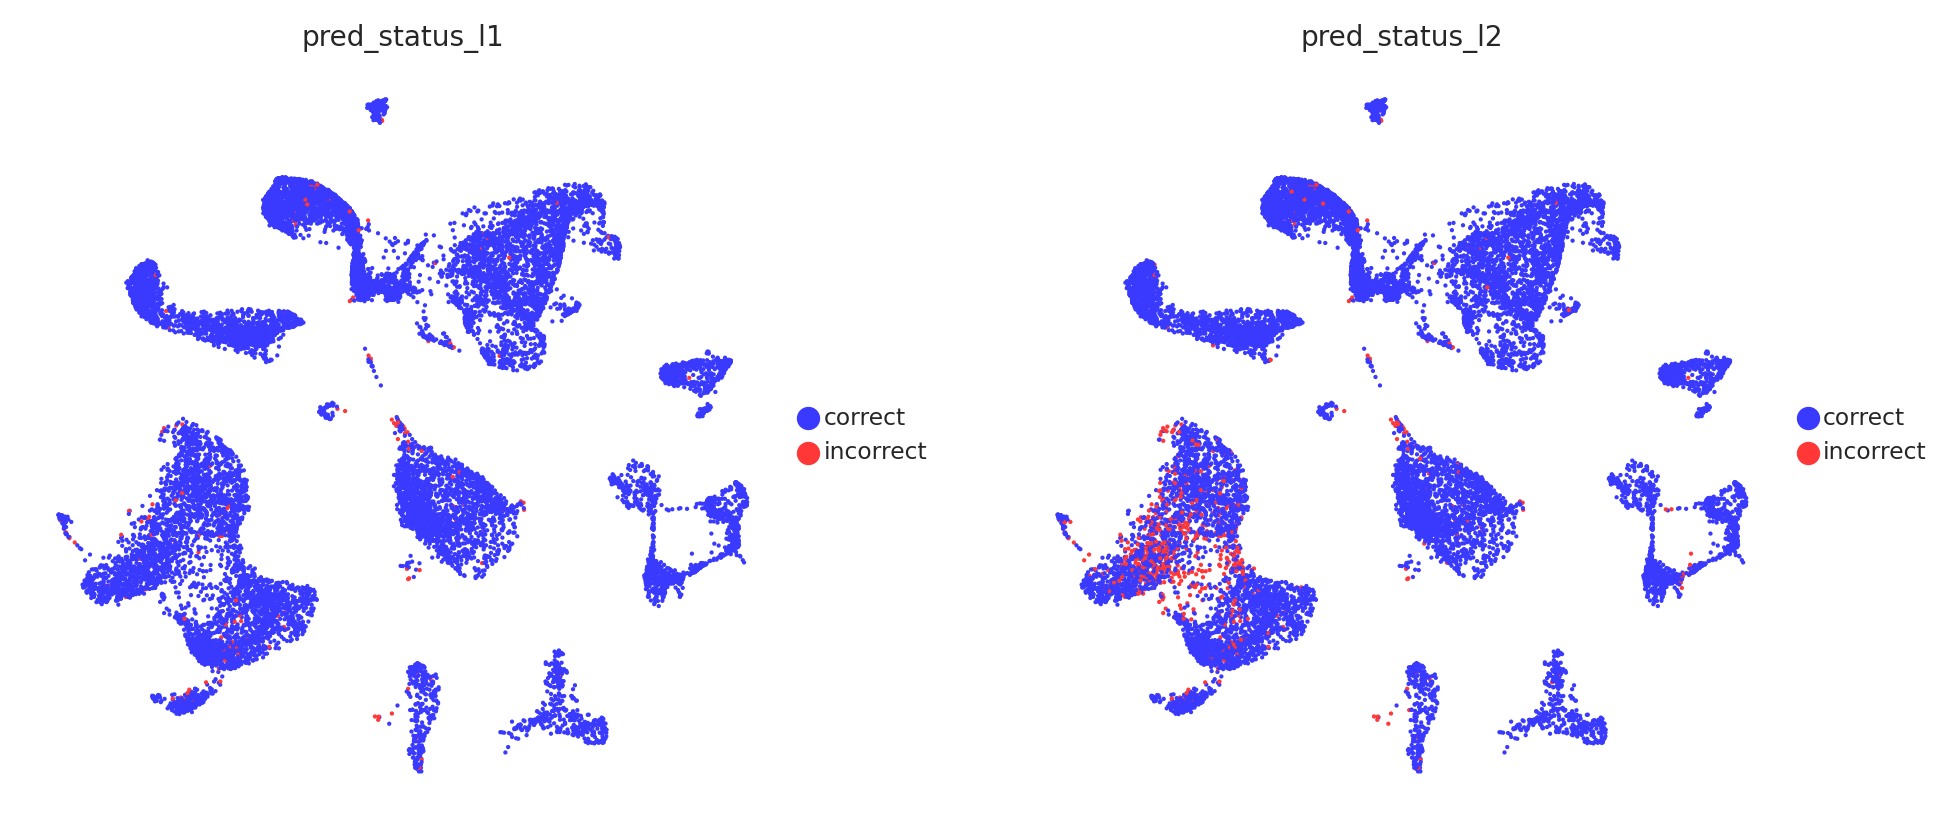
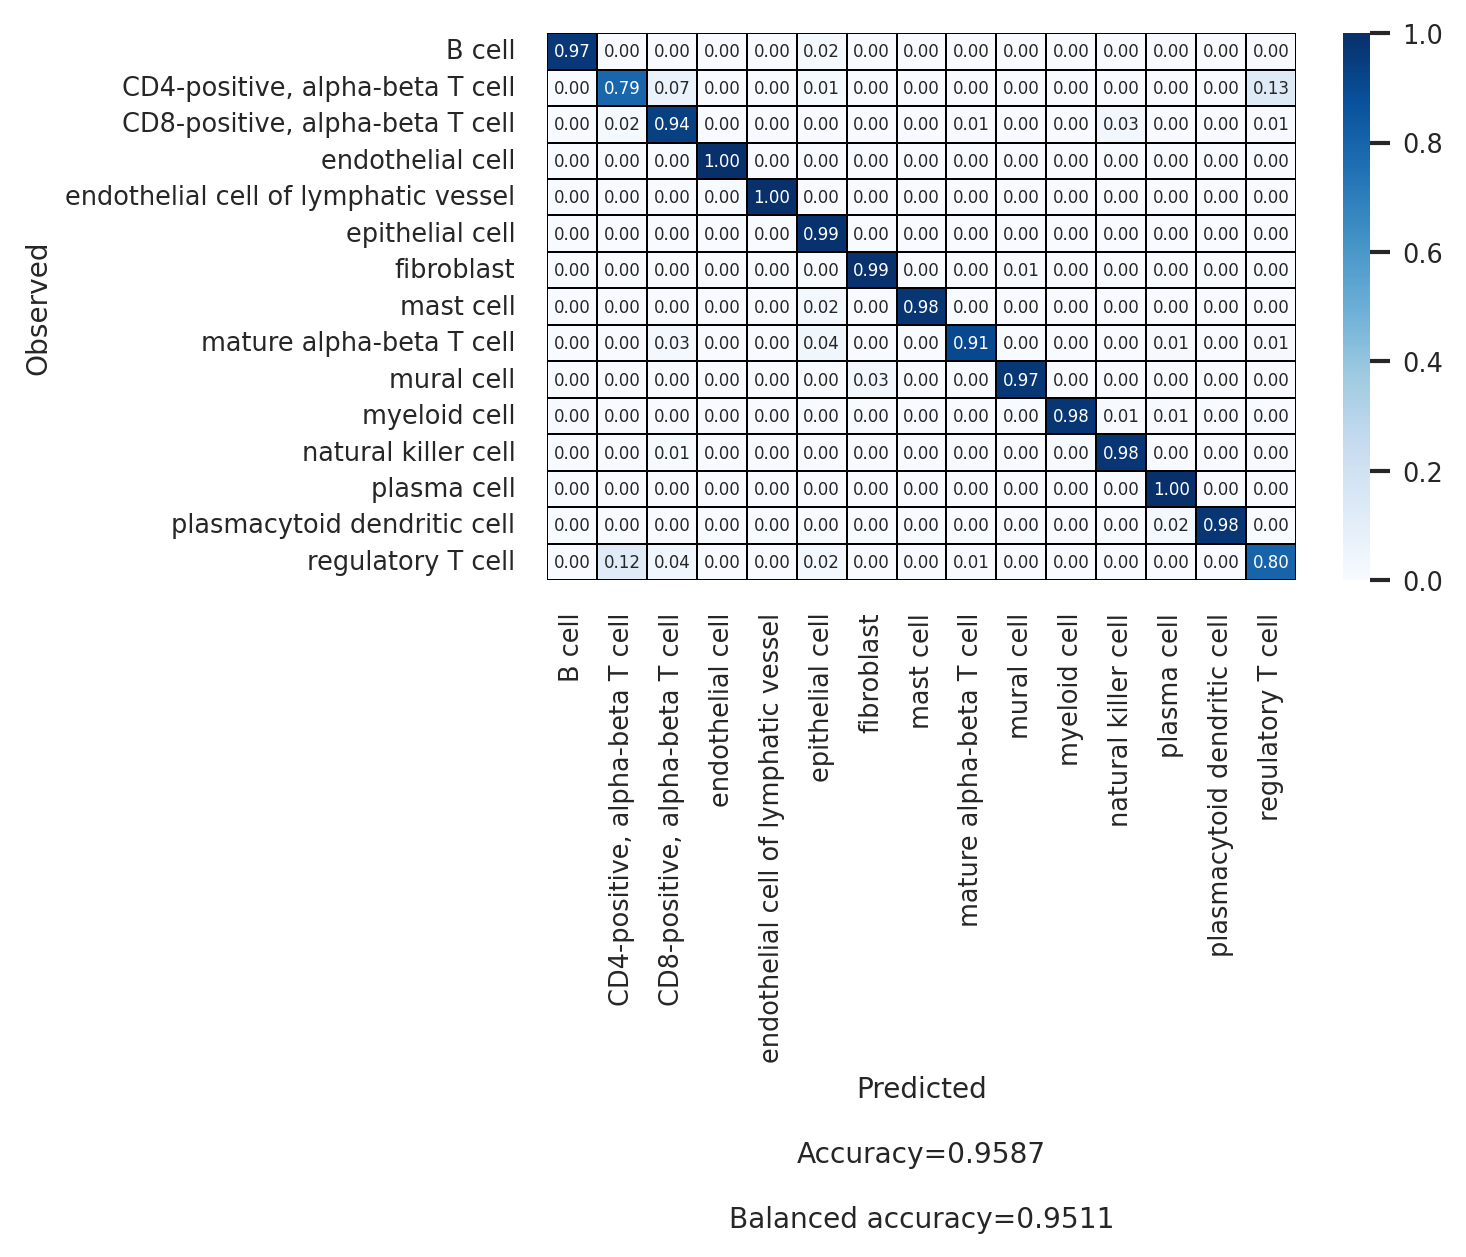
The probability and prediction status analysis indicates issues with the model in annotating T cell subtypes at the celltype_l2 annotation level. However, the model does not have problems with annotating other cell types, as confirmed by the quality analysis presented below.
Comparizon of observed and predicted cell type annotations#
To compare the actual and predicted cell types, we use report_classif_full and conf_matrix from the scNoah module. More information about the metrics in scparadise.scnoah.report_classif_full is available in the scParadise documentation. More information about confusion matrix (scparadise.scnoah.conf_matrix) is available
here.
[31]:
# First annotation level (celltype_l1)
df_l1 = scparadise.scnoah.report_classif_full(
    adata_test,
    celltype='celltype_l1',
    pred_celltype='pred_celltype_l1',
    ndigits = 3
)
df_l1
[31]:
| precision | recall/sensitivity | specificity | f1-score | geometric mean | index balanced accuracy | number of cells | |
|---|---|---|---|---|---|---|---|
| B | 0.991 | 0.986 | 0.998 | 0.989 | 0.992 | 0.983 | 3969 |
| Endothelial | 0.998 | 0.998 | 1.0 | 0.998 | 0.999 | 0.998 | 509 |
| Epithelial | 0.992 | 0.99 | 0.994 | 0.991 | 0.992 | 0.984 | 7505 |
| Myeloid | 0.979 | 0.981 | 0.999 | 0.98 | 0.99 | 0.978 | 924 |
| NK | 0.843 | 0.96 | 0.998 | 0.897 | 0.979 | 0.954 | 223 |
| Stromal | 0.999 | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | 1113 |
| T | 0.979 | 0.979 | 0.994 | 0.979 | 0.987 | 0.972 | 4057 |
| macro avg | 0.969 | 0.985 | 0.998 | 0.976 | 0.991 | 0.981 | |
| weighted avg | 0.987 | 0.987 | 0.996 | 0.987 | 0.991 | 0.982 | |
| Accuracy | 0.987 | ||||||
| Balanced accuracy | 0.985 |
[32]:
sns.set(font_scale = 0.7)
plt.figure(figsize = (3, 3))
scparadise.scnoah.conf_matrix(
    adata_test,
    celltype = 'celltype_l1',
    pred_celltype = 'pred_celltype_l1',
    annot_kws = {"size":5},
    linewidths = 0.1, linecolor = 'black',
    fmt =  ".2f",
    ndigits_metrics = 4,
    vmin = 0, vmax = 1
)
[33]:
# Second annotation level (celltype_l2)
df_l2 = scparadise.scnoah.report_classif_full(
    adata_test,
    celltype='celltype_l2',
    pred_celltype='pred_celltype_l2',
    ndigits = 3
)
df_l2
[33]:
| precision | recall/sensitivity | specificity | f1-score | geometric mean | index balanced accuracy | number of cells | |
|---|---|---|---|---|---|---|---|
| B cell | 0.995 | 0.971 | 0.999 | 0.983 | 0.985 | 0.968 | 2050 |
| CD4-positive, alpha-beta T cell | 0.861 | 0.801 | 0.988 | 0.83 | 0.89 | 0.777 | 1554 |
| CD8-positive, alpha-beta T cell | 0.917 | 0.949 | 0.991 | 0.933 | 0.97 | 0.936 | 1742 |
| endothelial cell | 0.996 | 1.0 | 1.0 | 0.998 | 1.0 | 1.0 | 457 |
| endothelial cell of lymphatic vessel | 1.000 | 0.981 | 1.0 | 0.99 | 0.99 | 0.979 | 52 |
| epithelial cell | 0.991 | 0.991 | 0.994 | 0.991 | 0.992 | 0.985 | 7505 |
| fibroblast | 0.982 | 0.994 | 0.999 | 0.988 | 0.997 | 0.993 | 676 |
| mast cell | 0.986 | 0.986 | 1.0 | 0.986 | 0.993 | 0.985 | 148 |
| mature alpha-beta T cell | 0.868 | 0.88 | 0.999 | 0.874 | 0.938 | 0.869 | 75 |
| mural cell | 0.991 | 0.973 | 1.0 | 0.982 | 0.986 | 0.97 | 437 |
| myeloid cell | 0.987 | 0.975 | 0.999 | 0.981 | 0.987 | 0.972 | 726 |
| natural killer cell | 0.830 | 0.964 | 0.998 | 0.892 | 0.981 | 0.959 | 223 |
| plasma cell | 0.985 | 0.997 | 0.998 | 0.991 | 0.998 | 0.996 | 1919 |
| plasmacytoid dendritic cell | 0.980 | 0.98 | 1.0 | 0.98 | 0.99 | 0.978 | 50 |
| regulatory T cell | 0.707 | 0.757 | 0.988 | 0.731 | 0.864 | 0.73 | 686 |
| macro avg | 0.939 | 0.947 | 0.997 | 0.942 | 0.971 | 0.94 | |
| weighted avg | 0.959 | 0.959 | 0.995 | 0.959 | 0.976 | 0.951 | |
| Accuracy | 0.959 | ||||||
| Balanced accuracy | 0.947 |
[34]:
sns.set(font_scale = 0.7)
plt.figure(figsize = (5, 3))
scparadise.scnoah.conf_matrix(
    adata_test,
    celltype = 'celltype_l2',
    pred_celltype = 'pred_celltype_l2',
    annot_kws = {"size":5},
    linewidths = 0.1, linecolor = 'black',
    fmt =  ".2f",
    ndigits_metrics = 4,
    vmin = 0, vmax = 1
)

[35]:
# Save anndata with predicted annotations
adata_test.write_h5ad('adata_test_imbalanced_model.h5ad')
[36]:
import session_info2
session_info2.session_info()
[36]:
| Package | Version |
|---|---|
| pandas | 2.3.3 |
| scanpy | 1.11.5 |
| scparadise | 1.2.0 |
| seaborn | 0.13.2 |
| matplotlib | 3.11.0 |
| numpy | 2.4.6 |
| anndata | 0.12.16 |
| Component | Info |
| Python | 3.11.15 (main, Jun 11 2026, 15:20:16) [GCC 14.3.0] |
| OS | Linux-6.8.0-138-generic-x86_64-with-glibc2.39 |
| Updated | 2026-09-03 21:11 |
Dependencies
| Dependency | Version |
|---|---|
| Cython | 3.3.0 |
| defusedxml | 0.7.1 |
| donfig | 0.8.1.post1 |
| dataclasses | 0.6 |
| Pygments | 2.20.0 |
| ipython | 9.14.1 |
| ipykernel | 7.3.0 |
| platformdirs | 4.10.0 |
| six | 1.17.0 |
| scikit-image | 0.26.0 |
| llvmlite | 0.47.0 |
| executing | 2.2.1 |
| jedi | 0.20.0 |
| h5py | 3.16.0 |
| numcodecs | 0.16.5 |
| python-dateutil | 2.9.0.post0 |
| patsy | 1.0.2 |
| narwhals | 2.22.1 |
| optuna | 4.9.0 |
| shap | 0.49.1 |
| sympy | 1.14.0 |
| wcwidth | 0.8.1 |
| matplotlib-inline | 0.2.2 |
| fonttools | 4.63.0 |
| pyparsing | 3.3.2 |
| pathlib | 1.0.1 |
| comm | 0.2.3 |
| torch | 2.12.0 (2.12.0+cu130) |
| parso | 0.8.7 |
| typing | 3.7.4.3 |
| charset-normalizer | 3.4.7 |
| zarr | 3.1.6 |
| umap-learn | 0.5.12 |
| scikit-misc | 0.5.2 |
| traitlets | 5.15.1 |
| leidenalg | 0.12.0 |
| asttokens | 3.0.1 |
| jupyter_core | 5.9.1 |
| joblib | 1.5.3 |
| kiwisolver | 1.5.0 |
| pyzmq | 27.1.0 |
| plottable | 0.1.5 |
| pure_eval | 0.2.3 |
| pillow | 12.2.0 |
| sparse | 0.18.0 |
| cloudpickle | 3.1.2 |
| lazy-loader | 0.5 |
| cycler | 0.12.1 |
| fsspec | 2026.4.0 |
| pytorch-tabnet | 4.1.0 |
| statsmodels | 0.14.6 |
| pytz | 2026.2 |
| PyYAML | 6.0.3 |
| setuptools | 81.0.0 |
| opt_einsum | 3.4.0 |
| prompt_toolkit | 3.0.52 |
| pynndescent | 0.6.0 |
| decorator | 5.3.1 |
| scverse-misc | 0.0.3 |
| google-crc32c | 1.8.0 |
| pyarrow | 24.0.0 |
| xarray | 2026.4.0 |
| cuda-bindings | 13.3.1 |
| debugpy | 1.8.21 |
| imbalanced-learn | 0.14.2 |
| jupyter_client | 8.9.1 |
| session-info2 | 0.4.1 |
| sklearn-compat | 0.1.6 |
| scipy | 1.17.1 |
| threadpoolctl | 3.6.0 |
| typing_extensions | 4.15.0 |
| mpmath | 1.3.0 |
| texttable | 1.7.0 |
| psutil | 7.2.2 |
| igraph | 1.0.0 |
| numba | 0.65.1 |
| stack-data | 0.6.3 |
| natsort | 8.4.0 |
| cuda-pathfinder | 1.5.5 |
| rich | 15.0.0 |
| tornado | 6.5.7 |
| legacy-api-wrap | 1.5 |
| packaging | 26.0 |
| cffi | 2.0.0 |
| colorlog | 6.10.1 |
| scikit-learn | 1.9.0 |
| argparse | 1.4.0 (1.1) |
| mudata | 0.3.8 |
| muon | 0.1.7 |
| pycparser | 3.0 (3.00) |
| tqdm | 4.68.2 |
| slicer | 0.0.8 |
| triton | 3.7.0 |
Copyable Markdown
| Package    | Version |
| ---------- | ------- |
| pandas     | 2.3.3   |
| scanpy     | 1.11.5  |
| scparadise | 1.2.0   |
| seaborn    | 0.13.2  |
| matplotlib | 3.11.0  |
| numpy      | 2.4.6   |
| anndata    | 0.12.16 |

| Dependency         | Version               |
| ------------------ | --------------------- |
| Cython             | 3.3.0                 |
| defusedxml         | 0.7.1                 |
| donfig             | 0.8.1.post1           |
| dataclasses        | 0.6                   |
| Pygments           | 2.20.0                |
| ipython            | 9.14.1                |
| ipykernel          | 7.3.0                 |
| platformdirs       | 4.10.0                |
| six                | 1.17.0                |
| scikit-image       | 0.26.0                |
| llvmlite           | 0.47.0                |
| executing          | 2.2.1                 |
| jedi               | 0.20.0                |
| h5py               | 3.16.0                |
| numcodecs          | 0.16.5                |
| python-dateutil    | 2.9.0.post0           |
| patsy              | 1.0.2                 |
| narwhals           | 2.22.1                |
| optuna             | 4.9.0                 |
| shap               | 0.49.1                |
| sympy              | 1.14.0                |
| wcwidth            | 0.8.1                 |
| matplotlib-inline  | 0.2.2                 |
| fonttools          | 4.63.0                |
| pyparsing          | 3.3.2                 |
| pathlib            | 1.0.1                 |
| comm               | 0.2.3                 |
| torch              | 2.12.0 (2.12.0+cu130) |
| parso              | 0.8.7                 |
| typing             | 3.7.4.3               |
| charset-normalizer | 3.4.7                 |
| zarr               | 3.1.6                 |
| umap-learn         | 0.5.12                |
| scikit-misc        | 0.5.2                 |
| traitlets          | 5.15.1                |
| leidenalg          | 0.12.0                |
| asttokens          | 3.0.1                 |
| jupyter_core       | 5.9.1                 |
| joblib             | 1.5.3                 |
| kiwisolver         | 1.5.0                 |
| pyzmq              | 27.1.0                |
| plottable          | 0.1.5                 |
| pure_eval          | 0.2.3                 |
| pillow             | 12.2.0                |
| sparse             | 0.18.0                |
| cloudpickle        | 3.1.2                 |
| lazy-loader        | 0.5                   |
| cycler             | 0.12.1                |
| fsspec             | 2026.4.0              |
| pytorch-tabnet     | 4.1.0                 |
| statsmodels        | 0.14.6                |
| pytz               | 2026.2                |
| PyYAML             | 6.0.3                 |
| setuptools         | 81.0.0                |
| opt_einsum         | 3.4.0                 |
| prompt_toolkit     | 3.0.52                |
| pynndescent        | 0.6.0                 |
| decorator          | 5.3.1                 |
| scverse-misc       | 0.0.3                 |
| google-crc32c      | 1.8.0                 |
| pyarrow            | 24.0.0                |
| xarray             | 2026.4.0              |
| cuda-bindings      | 13.3.1                |
| debugpy            | 1.8.21                |
| imbalanced-learn   | 0.14.2                |
| jupyter_client     | 8.9.1                 |
| session-info2      | 0.4.1                 |
| sklearn-compat     | 0.1.6                 |
| scipy              | 1.17.1                |
| threadpoolctl      | 3.6.0                 |
| typing_extensions  | 4.15.0                |
| mpmath             | 1.3.0                 |
| texttable          | 1.7.0                 |
| psutil             | 7.2.2                 |
| igraph             | 1.0.0                 |
| numba              | 0.65.1                |
| stack-data         | 0.6.3                 |
| natsort            | 8.4.0                 |
| cuda-pathfinder    | 1.5.5                 |
| rich               | 15.0.0                |
| tornado            | 6.5.7                 |
| legacy-api-wrap    | 1.5                   |
| packaging          | 26.0                  |
| cffi               | 2.0.0                 |
| colorlog           | 6.10.1                |
| scikit-learn       | 1.9.0                 |
| argparse           | 1.4.0 (1.1)           |
| mudata             | 0.3.8                 |
| muon               | 0.1.7                 |
| pycparser          | 3.0 (3.00)            |
| tqdm               | 4.68.2                |
| slicer             | 0.0.8                 |
| triton             | 3.7.0                 |

| Component | Info                                               |
| --------- | -------------------------------------------------- |
| Python    | 3.11.15 (main, Jun 11 2026, 15:20:16) [GCC 14.3.0] |
| OS        | Linux-6.8.0-138-generic-x86_64-with-glibc2.39      |
| Updated   | 2026-09-03 21:11                                   |